
Ayush Padvekar
0%

DATA ARCHITECT

2.8 Years Hands-On Experience

Architecting & scaling enterprise AWS data lakes and distributed PySpark pipelines processing 5M+ records daily. Proven record of cutting pipeline runtimes by 35% and accelerating executive decision intelligence.
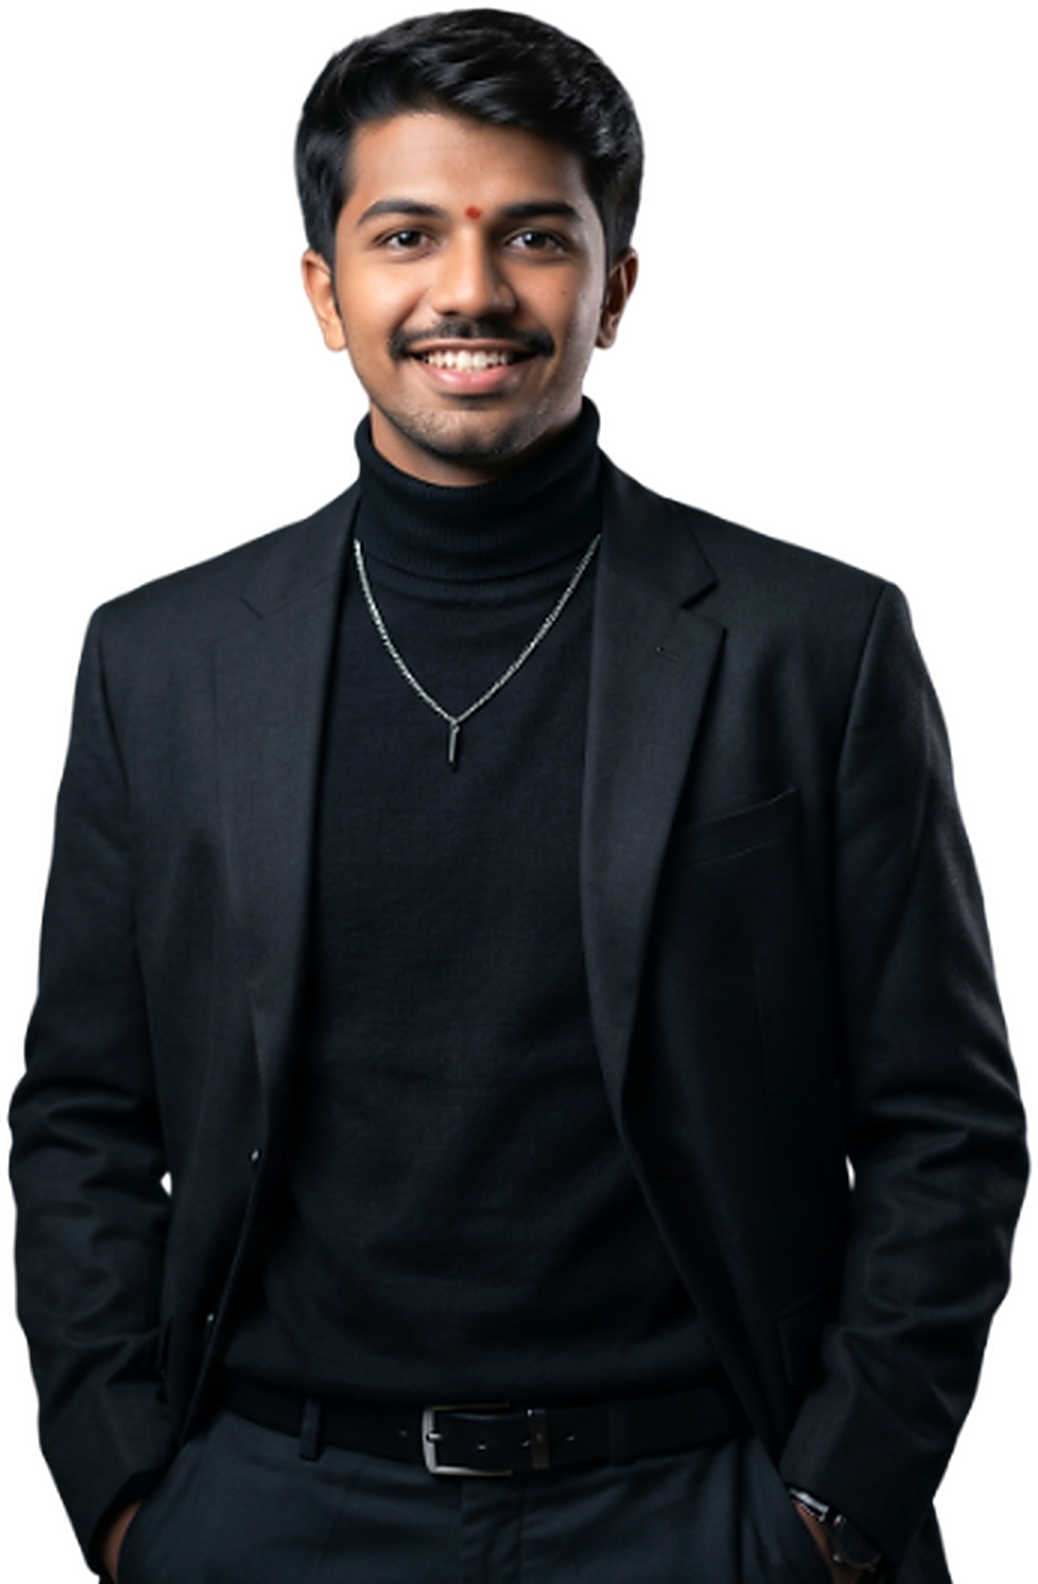
Ayush Padvekar

PADVEKAR

Scroll to explore data pipelines
Scalable Data Lakes
Distributed PySpark
5M+ Records/Day
AWS Cloud ETL
Power BI Dashboards
Automated Orchestration
Scalable Data Lakes
Distributed PySpark
5M+ Records/Day
AWS Cloud ETL
Power BI Dashboards
Automated Orchestration
Verified Track Record

Measured Production Impact.

5M+
Daily records ingested via AWS ETL
35%
Pipeline runtime optimization
20+
Enterprise BI dashboards deployed
99.9%
Pipeline availability & uptime
Architecture & Impact

Data systems are a competitive advantage.

With nearly 3 years of hands-on engineering experience at Metropolis Healthcare and beyond, I design resilient, fault-tolerant data architectures that transform disparate multi-source databases into centralized cloud data lakes and executive decision intelligence.

  • 01

    Engineer for fault tolerance

    Pipelines must heal themselves. Automated Step Functions state machines, error retries, and CloudWatch alarms turn unexpected failures into routine automated recovery.

  • 02

    Optimize at the compute layer

    Partitioned Parquet lakes, smart Athena indexing, and PySpark distributed transformations reduced daily pipeline execution runtime by 35%.

  • 03

    Pipelines serve decisions

    Petabytes of ingestion are useless without operational clarity. Every ETL job is designed backward from the executive dashboard to ensure sub-second decision speed.

  • 04

    Scale with distributed systems

    Monolithic scripts break under volume. I design distributed cloud ETL with AWS Glue, Lambda, and Spark to absorb sudden 10x spikes with zero manual intervention.

Technical Stack

Engineered for Big Data & Cloud

Big Data & Distributed ETL
PySpark AWS Glue ETL Development Data Modeling Data Lakes Apache Spark
Cloud Infrastructure (AWS)
Amazon S3 AWS Lambda Step Functions Amazon Athena Amazon EMR CloudWatch
Languages & Querying
Python Advanced SQL Pandas NumPy Git / Version Control
BI & Decision Analytics
Power BI Amazon QuickSight Tableau DAX Measures Advanced Excel
Professional Credentials

Licenses & Certifications.

Industry-verified credentials across Relational SQL, BigQuery analytics, business intelligence visualization, and distributed data manipulation.

Feb 2023

SQL for Data Science

University of California, Davis

May 2023

Google BigQuery & PostgreSQL : Big Query for Data Analysis

Start-Tech Academy

Aug 2022

Data Visualisation: Empowering Business with Effective Insights

Tata Technologies

Jul 2022

Data Manipulation in Python: Master Python, Numpy & Pandas

Udemy

Portfolio & Solutions

Featured Projects. Pipelines & Intelligence.

Production AWS data lakes, distributed PySpark pipelines, executive BI dashboards, and deep learning systems engineered for scale and sub-second decision-making. Click any project card to view full technical architecture and details.

AWS Enterprise Data Lake Data Engineering 5+ DBs Ingested

AWS Enterprise Data Lake & ETL

Centralized S3 Data Lake integrating 5+ DBs with automated PySpark pipelines, cutting silos by 40%.

AWS S3 PySpark Athena
Metropolis Healthcare Ingestion Data Engineering 5M+ Records/Day

Metropolis Healthcare Ingestion

High-throughput ingestion processing 5M+ records daily with automated retries and 35% runtime cut.
Python Athena Step Functions
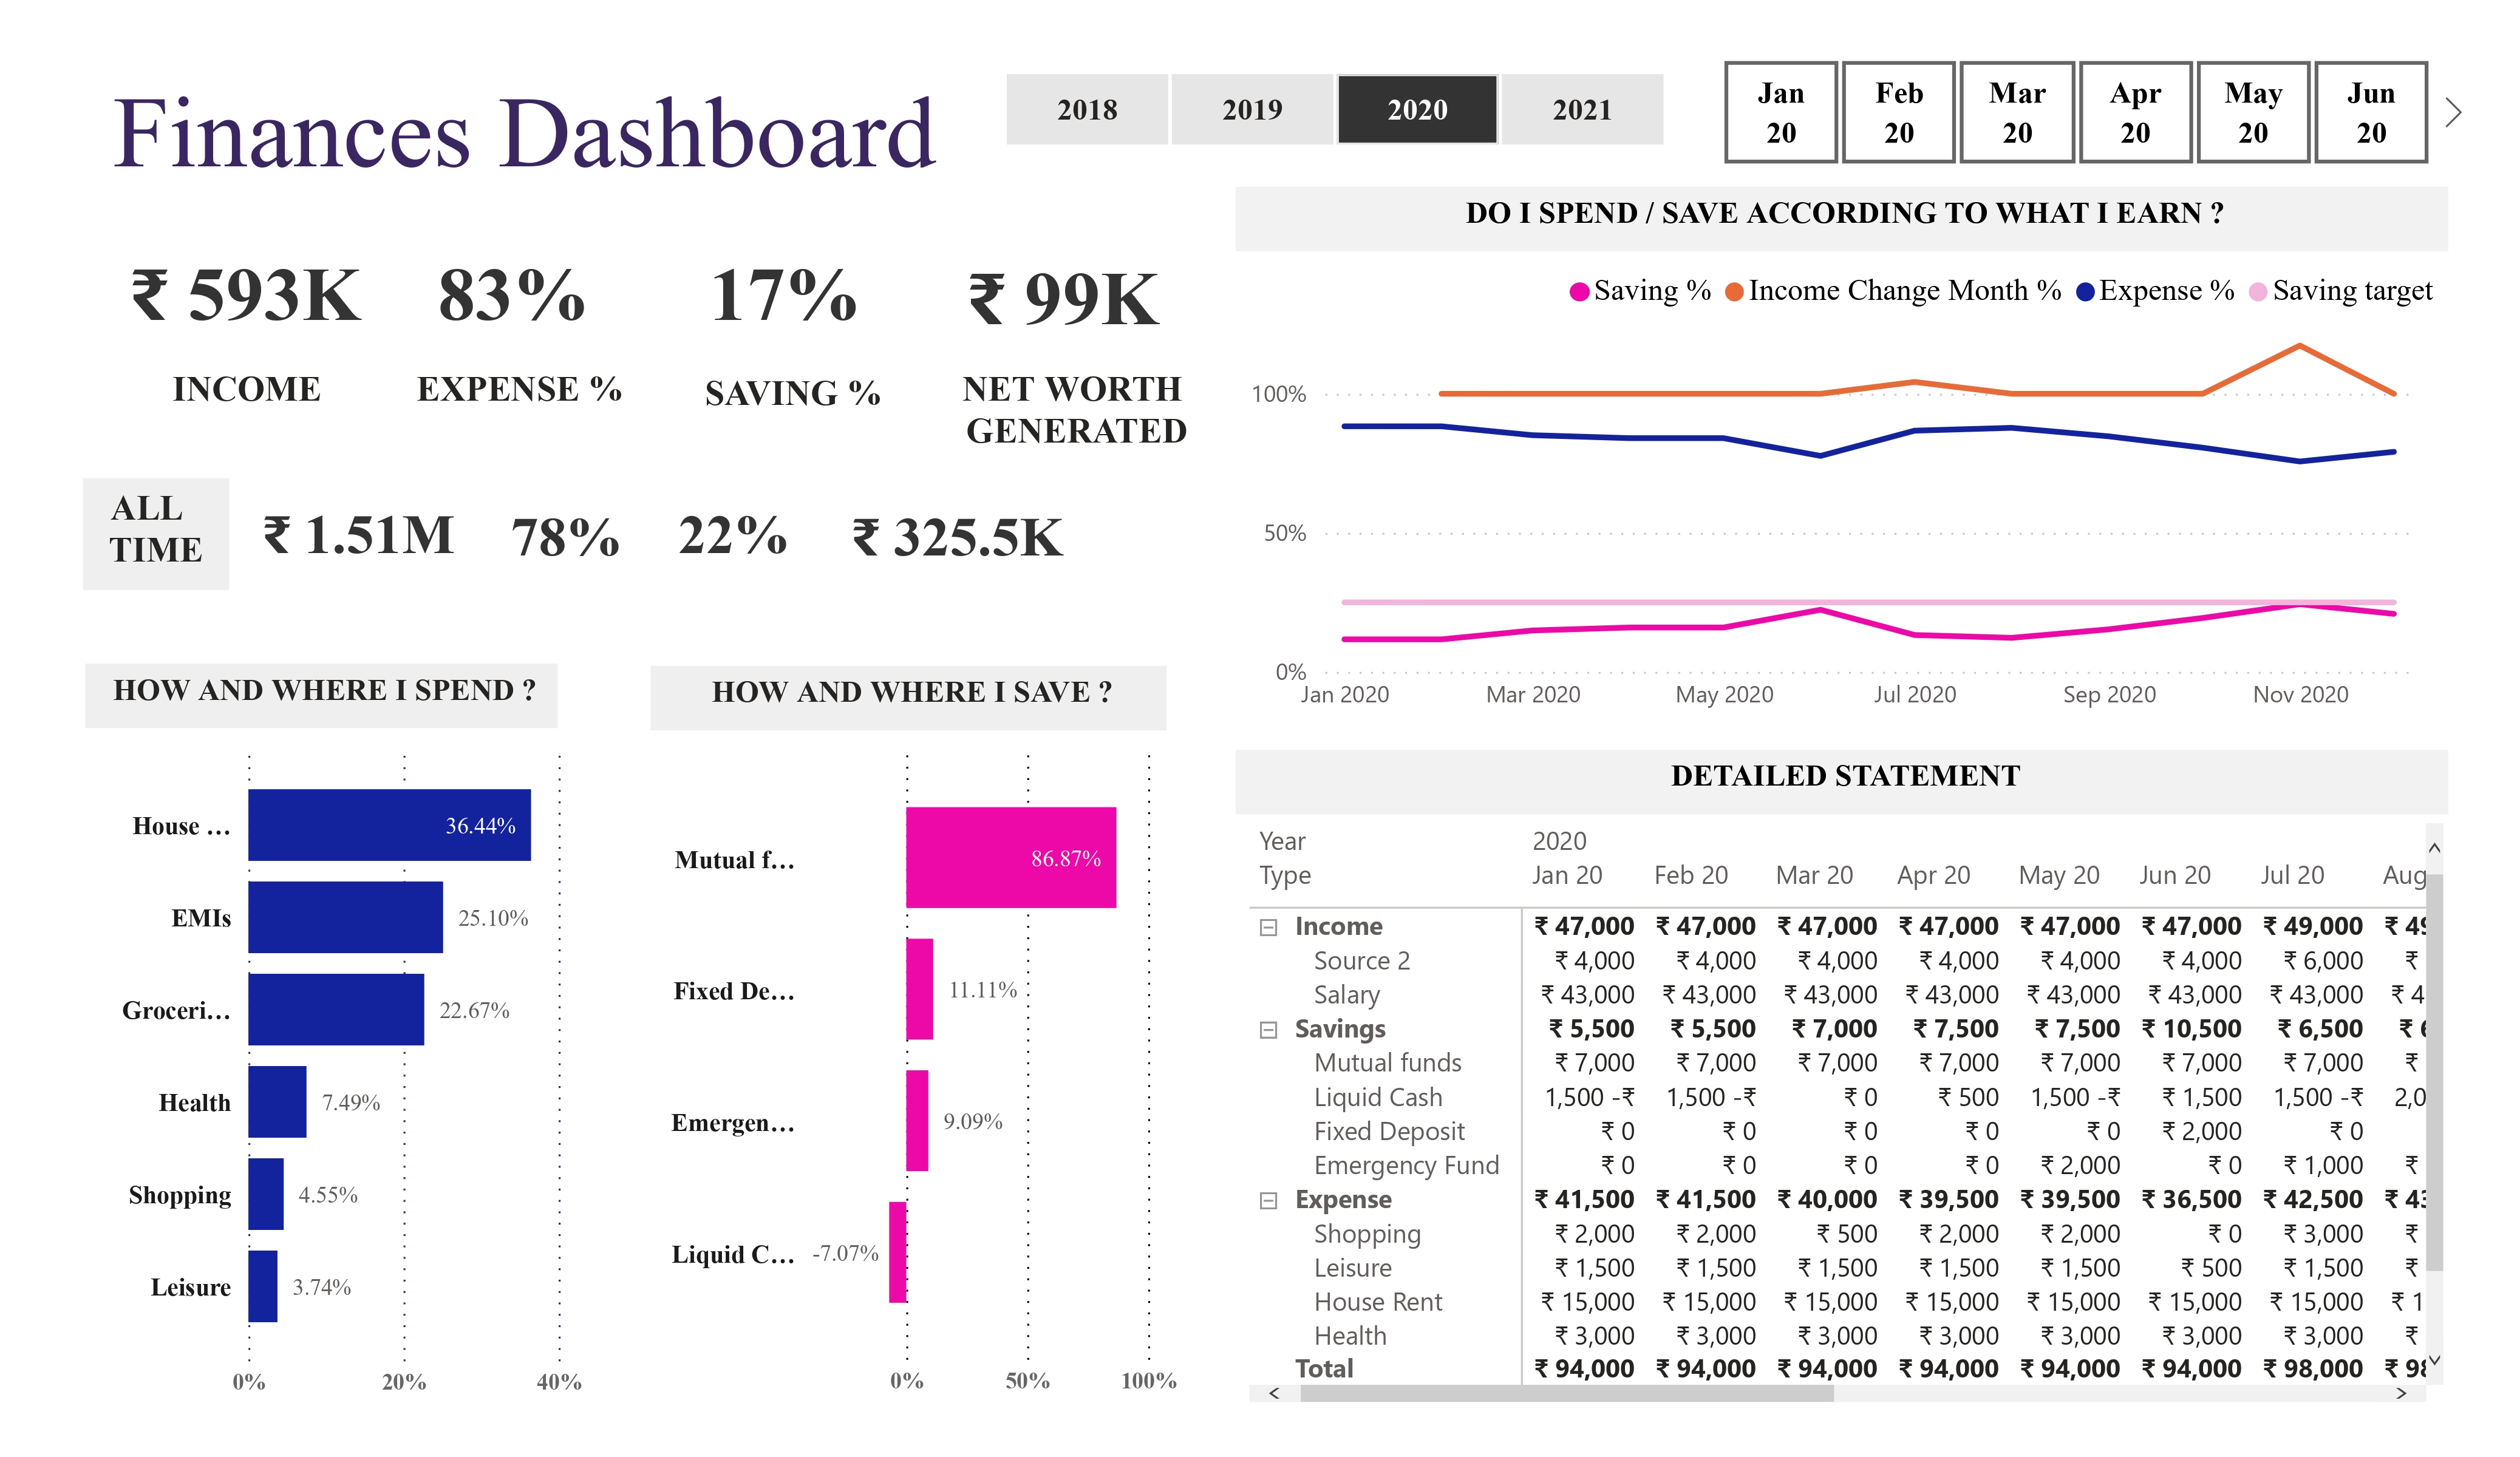
Personal Finances Intelligence Dashboard Power BI / DAX

Personal Finances Intelligence

Multi-source cash flow, savings rate, and portfolio allocation analytics with dynamic forecasting.
Power BI DAX Modeling
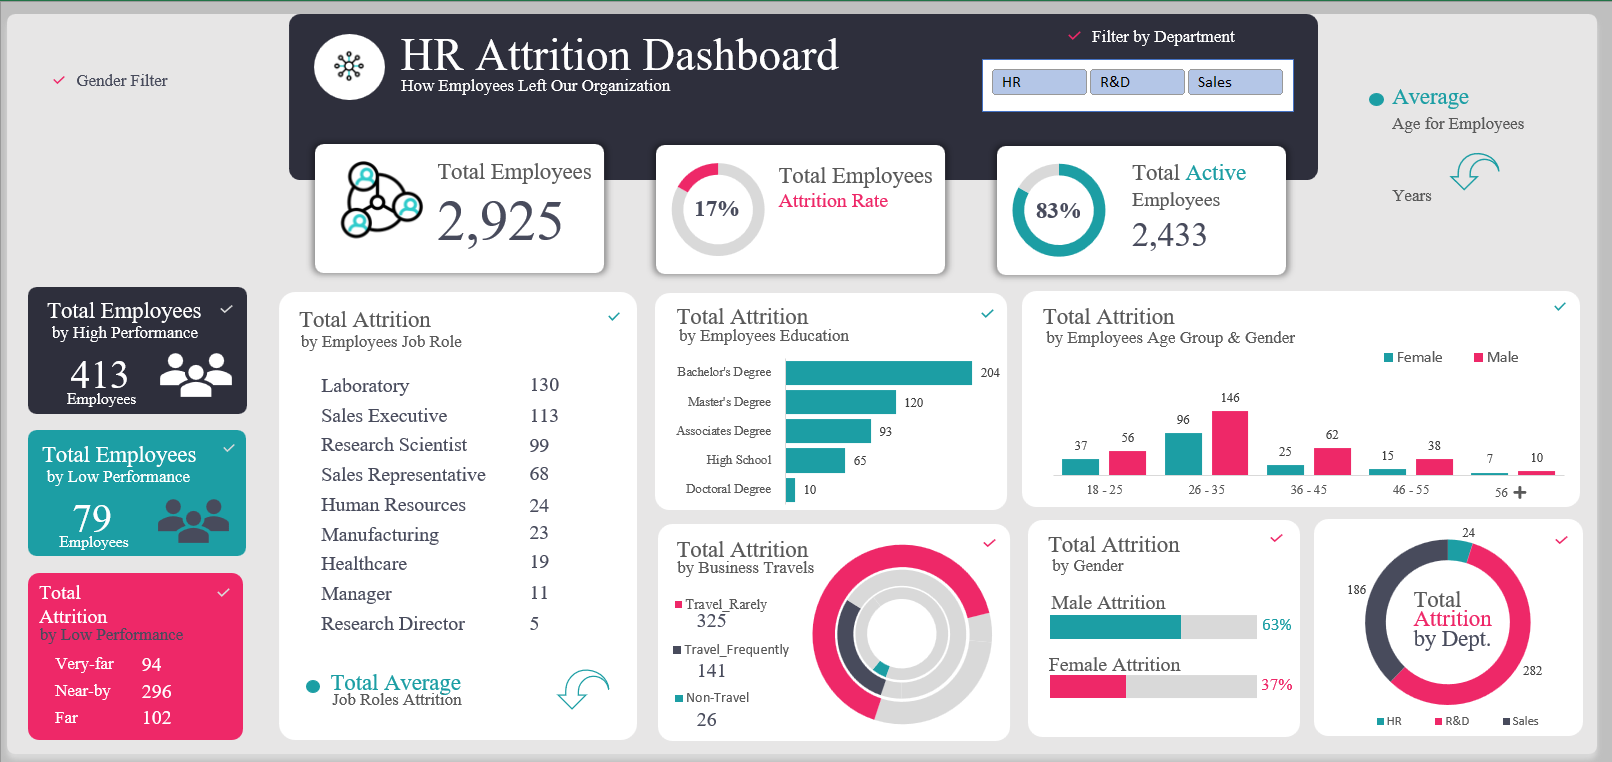
Enterprise HR Attrition Dashboard Workforce BI

Enterprise HR Attrition Analytics

Workforce retention dashboard mapping attrition drivers across roles, salaries, and satisfaction.
Power BI HR KPIs DAX
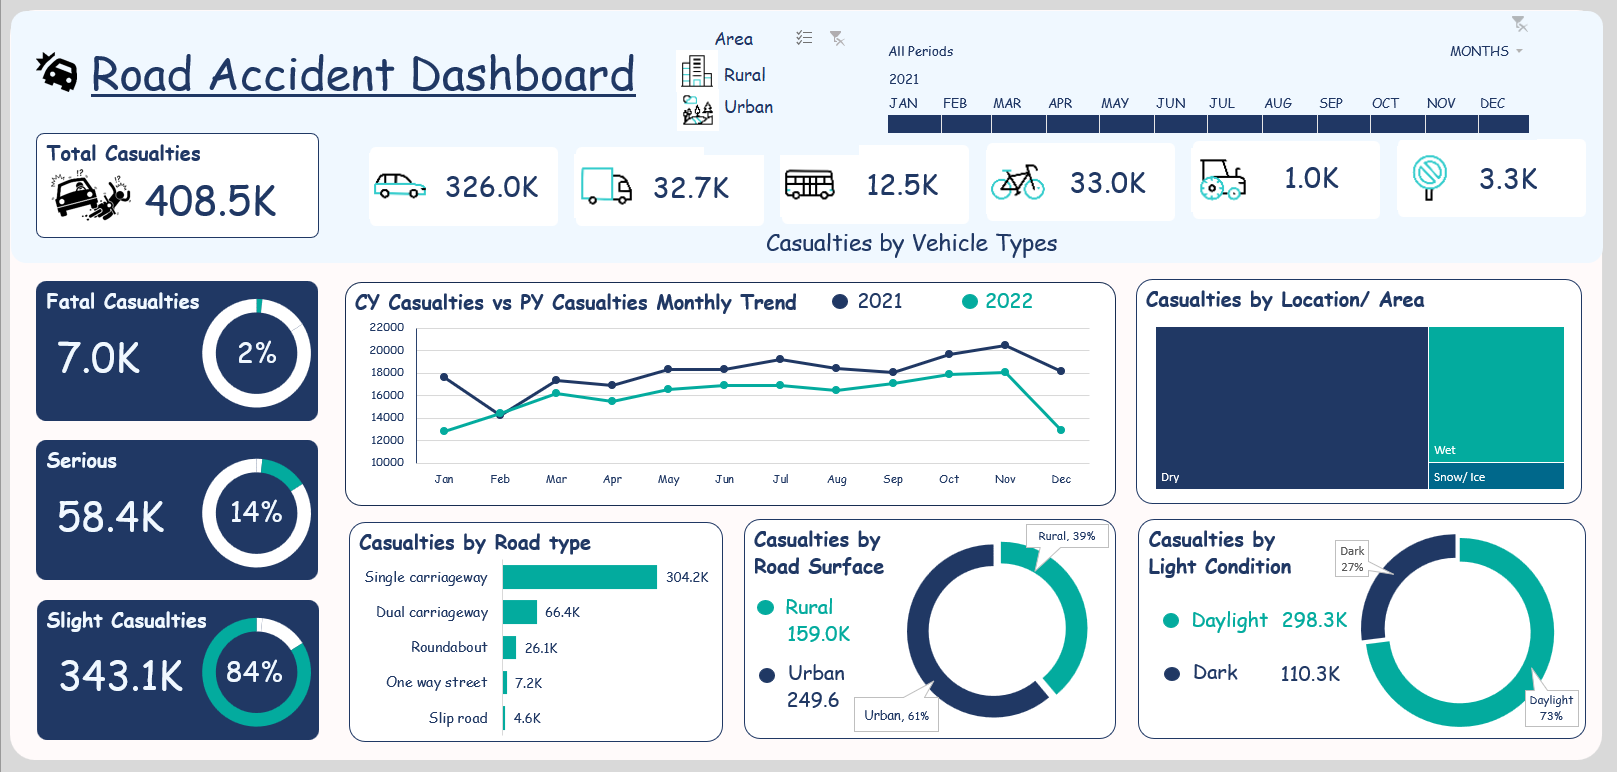
Road Accident Geospatial Dashboard Geospatial KPIs

Road Accident Geospatial & Safety

Multi-year urban traffic collision analytics highlighting peak risk conditions and safety interventions.

Power BI Maps Safety
Vehicle Detection Machine Learning 92% Acc @ 25+ FPS

Vision Vehicle Counting System

YOLOv8-based traffic video pipeline with 92% accuracy at 25+ FPS, automating multi-lane counting.

YOLOv8 OpenCV Python
Spam Email Detection Deep Learning 94% Accuracy

Deep Learning Spam Detection

LSTM & Bi-LSTM NLP neural networks reaching 94% accuracy, cutting false positives by 22%.
TensorFlow LSTM NLP
Stock Price Prediction App Machine Learning Streamlit App

Stock Price Prediction App

LSTM neural networks and regression forecasting market feeds deployed inside an interactive Streamlit app.

Streamlit LSTM Scikit
Professional History

Work Experience.

Hands-on engineering experience designing enterprise cloud data lakes, orchestrating distributed ETL workloads, and delivering analytics to senior stakeholders.
Metropolis Healthcare Limited Logo
Enterprise Production Role

Data Engineer

Metropolis Healthcare Limited • Full-time • Mumbai, India
Mar 2024 – Present

Leading cloud data lake operations and daily automated ETL ingestion across nationwide diagnostic centers, turning massive healthcare feeds into high-fidelity reporting tables and executive decision dashboards.
  • ▹
    Cloud Pipeline Ingestion: Built and scaled automated AWS ETL pipelines (S3, Glue, Lambda, Step Functions) processing 5M+ records daily across 5+ source relational databases, reducing data silos by 40% and cutting manual reporting effort by 40%.
  • ▹
    Compute & Query Optimization: Optimized PySpark distributed transformations and Athena SQL queries, reducing daily pipeline execution runtime by 35% and accelerating operational and financial reporting cycles.
  • ▹
    Decision Intelligence Dashboards: Designed, deployed, and maintained 20+ production Power BI & QuickSight dashboards for 10+ stakeholder groups across executive, operational, and laboratory divisions, reducing decision turnaround time by 25%.
  • ▹
    Reliability & Orchestration: Architected automated workflow orchestration, error retry state machines, and CloudWatch alert integrations via SNS, maintaining 99.9% pipeline uptime and availability.
Core Tech Stack:
AWS S3 AWS Glue PySpark Step Functions Amazon Athena AWS Lambda Python Advanced SQL Power BI Amazon QuickSight CloudWatch
EduRiser Learning Solutions Logo
Analytics Internship

Data Analytics Intern

EduRiser Learning Solutions • Internship • Mumbai, India
Jun 2023 – Aug 2023 • 3 mos

Spearheaded analytical dashboard development and enterprise business intelligence adoption to measure and optimize student learning engagement across multiple digital curricula.
  • ▹
    Performance Dashboards: Developed 8+ interactive Power BI dashboards tracking key student learning metrics and course progress, boosting reporting efficiency by 50%.
  • ▹
    Engagement Analytics: Analyzed multi-grade student engagement datasets across departments to identify friction points and guide content optimization.
  • ▹
    BI Best Practices & Modeling: Introduced Power BI to the analytics team, establishing data modeling standards and authoring reusable DAX measures for recurring KPI calculations.
Core Tech Stack:
Power BI DAX Data Modeling Advanced Excel SQL Business Intelligence
Academic Foundations

Education & Degrees.

D.Y. Patil International University

MCA — AI & Data Science

D.Y. Patil International University, Pune

Specialized in Distributed Big Data Computing, Cloud Architecture, Machine Learning, Deep Learning, and Enterprise Database Systems.
2022 – 2024 8.21 CGPA
Mumbai University

B.Sc. in Information Technology

D.G. Ruparel College (Mumbai University)

Graduated with Distinction. Comprehensive coursework in Relational Database Management (RDBMS & SQL), Data Structures, Computer Networks, and Software Development.

2019 – 2022 8.54 CGPA